Understand and plan
Recover the selected claim and translate the frozen specification into a feasible experimental pipeline.
Agent capability boundary benchmark
An Agent Capability Boundary Benchmark for Complex Paper-to-Code Reproduction
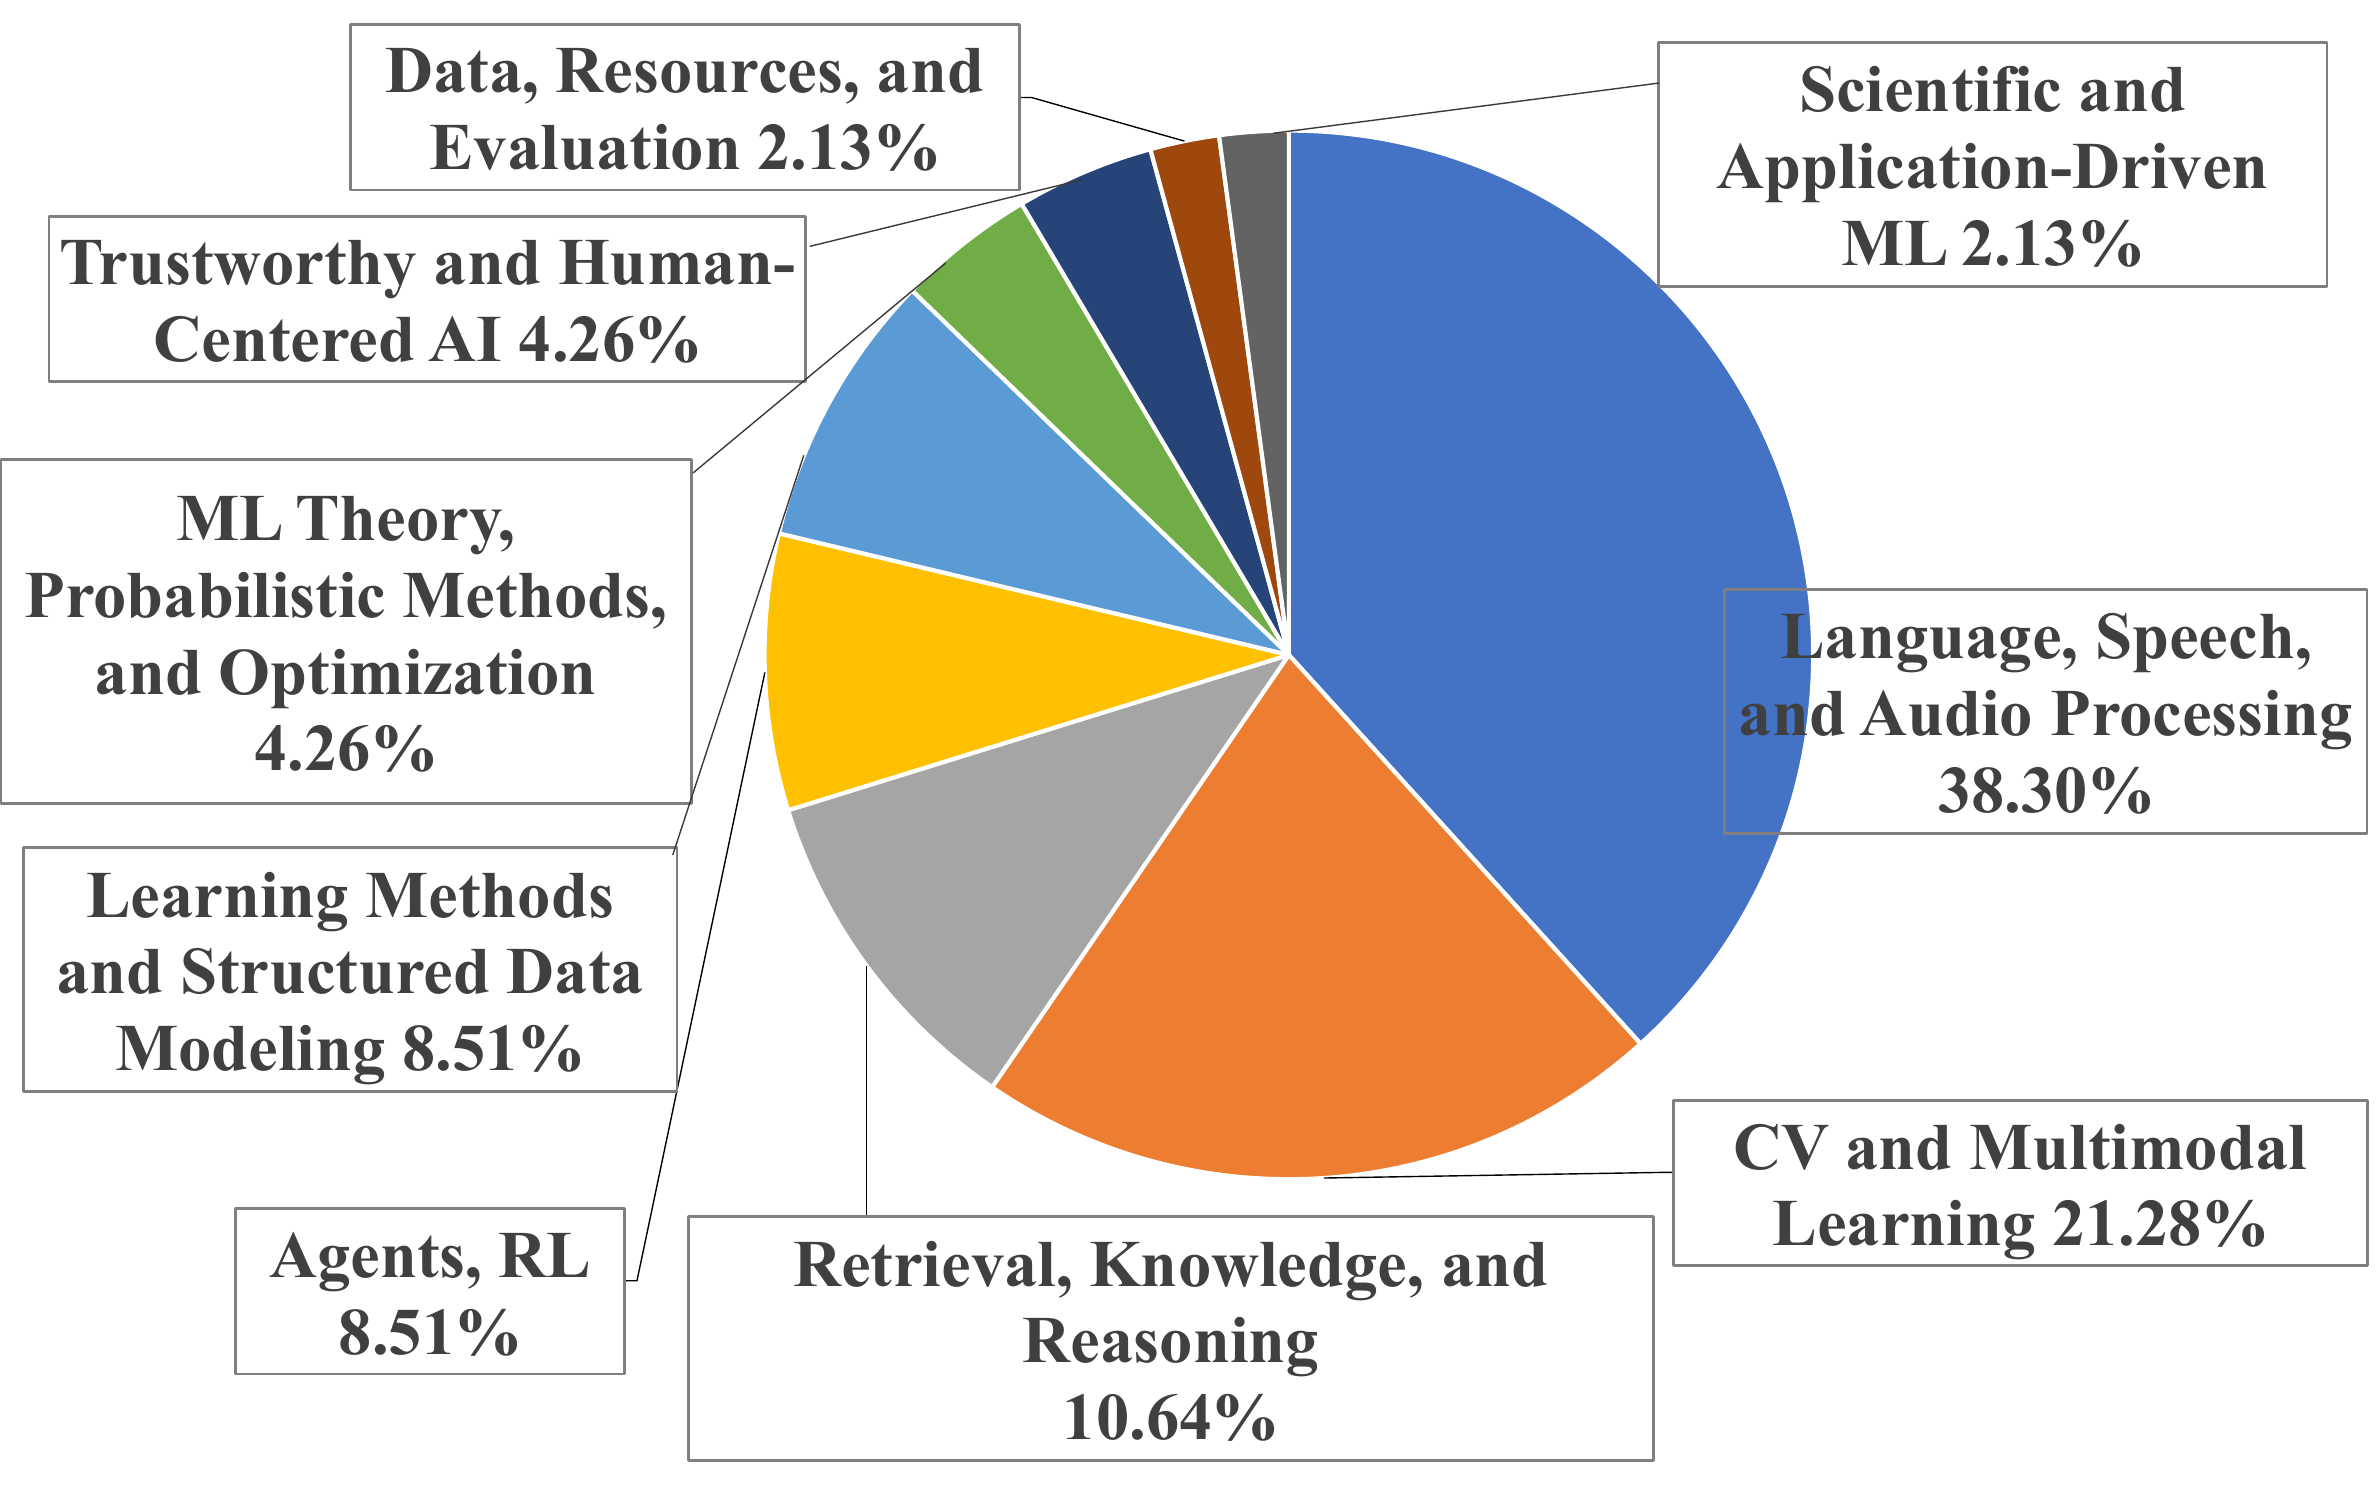
47 tasks · 9 model-agent settings · 423 trajectories · 15 domains
Reproducing a machine-learning paper requires more than generating plausible code. An agent must recover the target claim, respect the experimental contract, complete every required stage, and deliver artifacts whose reported metric can be independently checked. ReproBoundary evaluates this end-to-end capability across 47 frozen paper-to-code tasks.
Each task fixes the source repository and revision, data scope, required stages, compute budget, target metric, reference value, and evaluator before the run begins. Twenty tasks retain the paper-selected experimental scale; 27 reduce training, search, or repetition while keeping the complete target evaluation set.
Scope. Each task reproduces one selected result under a fixed resource limit. It does not reproduce every result or support every conclusion in the source paper.
A frozen task contract connects the paper claim, agent execution, delivered artifacts, and independent verification.
Recover the selected claim and translate the frozen specification into a feasible experimental pipeline.
Complete every required stage within the declared compute, time, memory, and storage envelope.
Retain traceable outputs and process evidence rather than treating a plausible final report as success.
Check artifact completeness and metric agreement separately with the frozen task-specific evaluator.
Browse all frozen tasks by paper, domain, target metric, dataset, or experimental scale.
Loading task inventory...
| Paper and target task | Domain | Target metric | Scale | Budget | Source repository |
|---|
GitHub hosts the lightweight task definitions, evaluator records, protocol templates, and verification code. Hugging Face hosts 423 cleaned, compressed execution logs with a central provenance index and SHA-256 fingerprints.
git clone https://github.com/ReproBoundary/ReproBoundary.git
cd ReproBoundary
python3 scripts/verify_release.py

# verification OK: tasks=47 evaluators=47 trajectory_records=423 bundled_logs=0
Evidence boundary. The logs support chronology, tool-use, failure, and release-integrity analysis. They do not include checkpoints, predictions, model weights, or training states and cannot by themselves replay most scientific metrics.
The public leaderboard is pending publication of frozen, provenance-checked aggregates. No provisional result is presented as a verified benchmark score.
Send the evaluated configuration, result files, and a link to supporting artifacts for verification.
endlesssalaxy@outlook.com